5 Must-Check Criteria Before Adopting a RAG Pipeline Document Parsing Solution
If your RAG pipeline quality isn’t meeting expectations, the cause is likely not the LLM but the very first stage: document parsing. When table row/column relationships are lost and hierarchical structure disappears before embedding, even a high-performance model will struggle to improve retrieval quality.
In this article, we’ll summarize five criteria you must check before adopting a document parsing solution, along with common pitfalls that are often missed in the field.
RAG Pipeline Performance Starts with Document Parsing
Parsing sits at the very front of the RAG pipeline, but it has the greatest impact on overall retrieval quality. How you structure documents changes chunking, embeddings, and retrieval accuracy in a chain reaction.
Why isn’t text extraction alone enough in a RAG pipeline?
Extracting text alone strips away table row and column relationships, heading and body hierarchy, and image context. When table structure is lost, the LLM misinterprets numbers; when hierarchy is lost, chunking goes off track and irrelevant chunks get retrieved.
The process of converting unstructured documents into structured data goes beyond simply extracting text; it involves preserving the document’s structure and context. Extracting characters and preserving a document’s logical structure are distinct processes, and this difference impacts the overall RAG retrieval quality.
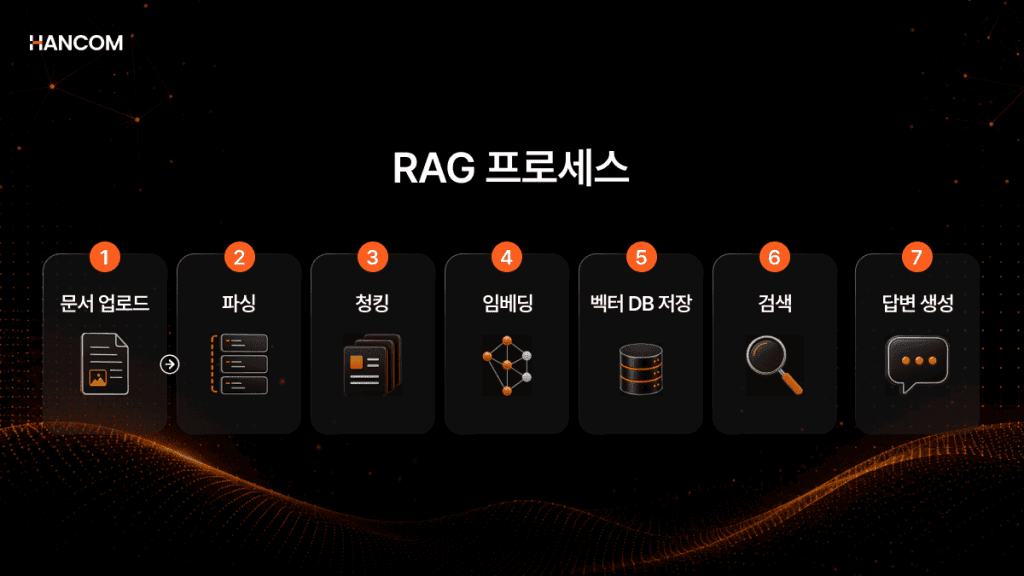
Flow connecting chunking, embedding, and retrieval after document parsing in a RAG pipeline
The RAG process runs in the following order: document extraction → parsing → chunking → embedding → vector DB storage → retrieval → LLM answer.
Because each stage is connected in series, it’s difficult to undo quality issues introduced during parsing in later stages. Since chunking strategy also changes depending on the output format (JSON/HTML), the choice of parsing method affects the design of the entire pipeline.
How Document Parsing Methods Affect Quality Across Every Stage of the RAG Pipeline
If documents are parsed in a way that’s hard for AI to read, chunking boundaries go off track, embedding quality drops, and retrieval results become inaccurate. Even with a good LLM, if it receives poorly parsed data as input, it can’t perform to its full potential.
In the “Revolutionizing Retrieval (2024)” study, a RAG system using a structure-aware parser showed higher answer accuracy than a system based on a general parser, with performance improvements confirmed on about 47% of questions. This result shows that improving RAG performance doesn’t have to start only with swapping LLMs or advancing models—significant gains can also come from improving document parsing and structure analysis quality alone.
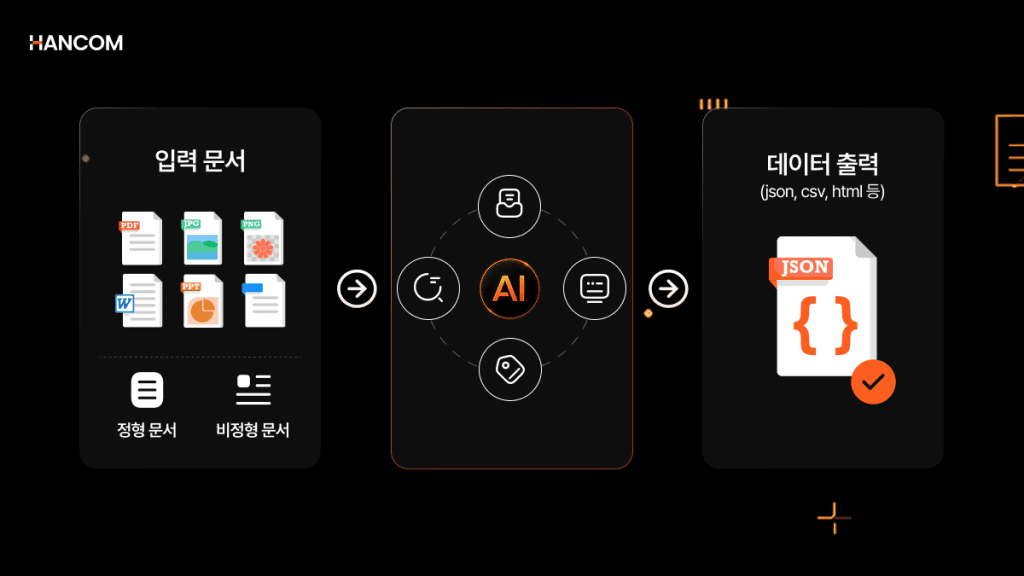
Criteria for Choosing a RAG Pipeline Document Parsing Solution
When choosing a document parsing solution, there are five criteria you must check: supported format coverage, structural extraction accuracy, preservation of hierarchical structure, support for security environments, and pipeline integration method. If even one doesn’t match your deployment environment, it can lead to a full rebuild after implementation.
✅ Supported Format Coverage of a Document Parsing Solution: From PDF to HWP/HWPX and Office
First, check whether it natively supports all document formats used in your environment. In particular, for HWP/HWPX, the key is not simple conversion but whether it can read and extract the original structure as-is.
A workaround that converts files to PDF causes formatting, footnotes, and equations to be lost together—and once information is lost, it cannot be recovered in later stages. In Korean public-sector and enterprise environments, HWP/HWPX documents are widely used, so how accurately the solution can process these formats is the first thing you should verify.
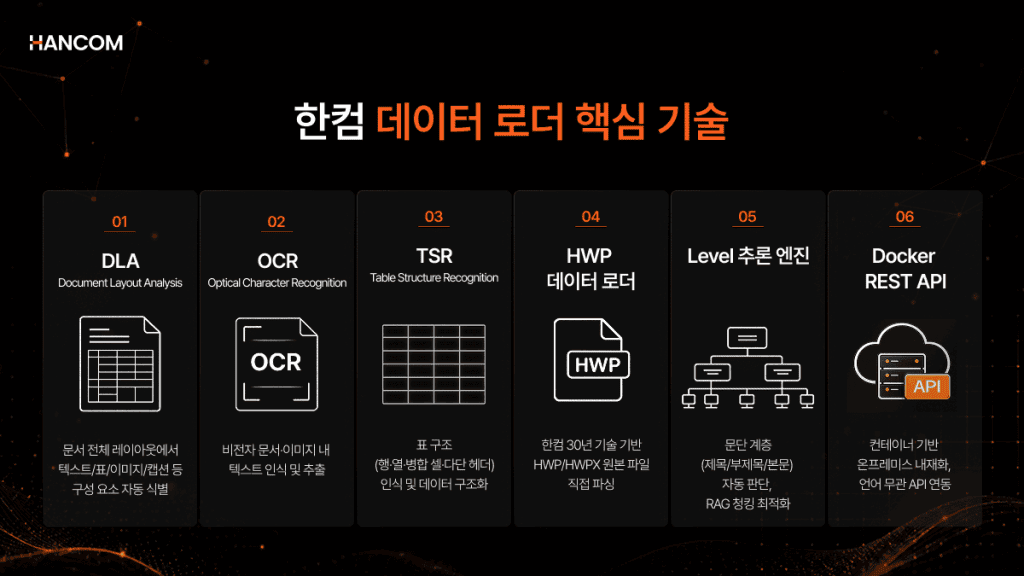
This is where Hancom Data Loader has a clear differentiator. Because it parses based on proprietary HWP SDK core technology, it extracts the original structure of HWP documents as-is without converting to PDF. It also minimizes loss of document layout and formatting information such as track changes, footnotes, equations, and indentation.
✅ Structural Extraction Accuracy: Document Layout Analysis and Table/Image Handling
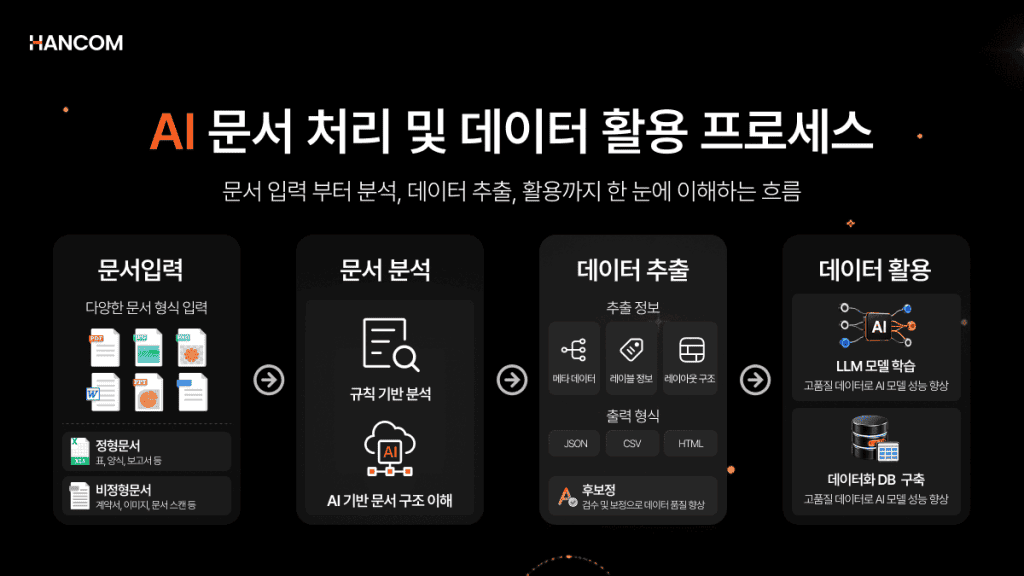
OCR (Optical Character Recognition) alone isn’t enough. To properly process documents that include multi-column layouts, merged cells, and nested tables, DLA (Document Layout Analysis), TSR (Table Structure Recognition), and OCR must work together within a single pipeline.
If these technologies are separated, multi-column layouts and captions get mixed up, and row/column relationships in merged cells are lost—so the LLM can’t interpret the numbers in tables accurately.
Hancom Data Loader internalizes DLA, TSR, and OCR into a single pipeline without external dependencies.
※ The Image Captioning feature is currently in the PoC stage, and the commercial release schedule will be announced later.
✅ Preserving Document Hierarchy That Determines RAG Pipeline Chunking Quality
Headings, subheadings, and body hierarchy must be preserved during the parsing stage for chunking to occur in meaningful units and for search accuracy to improve. If the hierarchy is lost, conditional logic such as ‘Article 3, Paragraph 2’ gets separated into multiple chunks, causing the LLM to read only fragmented content without context. This difference is particularly pronounced in Korean official documents and statutes, where indentation-based hierarchy is crucial.
Hancom Data Loader’s Level inference engine automatically tags hierarchy levels by analyzing paragraph styles, indentation, and numbering systems. It’s designed to recognize the hierarchical structures unique to Korean official documents and reports, making it a structure specialized for domestic public and administrative document processing.
✅ Security Environment and Deployment Method for a Document Parsing Solution
First, check whether documents can be processed within the internal network without being sent to an external cloud. With a cloud API approach, external transmission of documents is structurally unavoidable, so organizations that require network segmentation—such as public sector, finance, and legal—often cannot adopt it at all. Whether on-premises deployment is supported can be the first criterion to check in your evaluation.
Hancom Data Loader is designed to be fully self-contained within an internal network via a container-based REST API, preventing external leakage of documents. The Data Loader API provided as SaaS can be used immediately through API integration without a separate installation process, making it suitable for environments with relatively flexible security requirements or for running pilot tests.
✅ Check the RAG Pipeline Integration Method
Check whether parsing outputs are provided in structured formats such as JSON and HTML, and whether REST API and container-based support are available. If the output format doesn’t fit, additional development effort is required for pipeline integration, affecting both schedule and cost.
💡 Direct parsing of original HWP/HWPX, a single DLA·TSR·OCR pipeline, fully on-premises (self-contained) deployment
Want to solve all three in one? 👉 Explore Hancom Data Loader
Precautions Before Adopting a RAG Pipeline Document Parsing Solution
You need to verify format support, on-premises dependency structure, and actual document test results yourself. Features listed in the spec often behave differently in practice, and if you discover this difference after implementation, you may have to start over from scratch.
Check the Gap Between “HWP/HWPX Parsing Supported” Claims and Actual Processing Methods
Most solutions indicate HWP/HWPX support, but in practice, they use a workaround that converts files to PDF for processing. During conversion, tables are often converted into images, preventing Table Structure Recognition (TSR) from functioning, and formatting such as footnotes and indentation is lost and cannot be recovered. Since a ‘HWP/HWPX supported’ label alone doesn’t clarify whether it’s direct parsing of the original or a conversion workaround, you must verify the processing method yourself.
Before Adopting an On-Premises Document Parsing Solution, Check for External Dependencies
There are also solutions that outwardly claim to be on-premises but internally utilize external OCR APIs or cloud models. In such cases, documents leave the internal network, failing to meet security requirements. It is crucial to directly verify the technical architecture to ensure that the OCR, DLA, and TSR engines are all fully internalized.
Problems That Occur When You Adopt a Document Parsing Solution Based Only on Specs
Even if a solution supports features as listed in the spec, when you apply it to the actual documents you have, extraction quality may differ from expectations. Tables with many merged cells, multi-column layouts, and PDFs mixed with scanned pages show significantly different results from standard test documents.
You must test with actual document samples you have and allow plenty of time for a pilot period to reduce the risk of having to redo work later. If you build RAG with low parsing quality, you’ll end up having to redo all the downstream stages—chunking, embedding, and retrieval.
Start RAG Pipeline Document Parsing with Hancom Data Loader
Hancom Data Loader is a document parsing solution that converts HWP, HWPX, PDF, OOXML, and more into structured data, eliminating the burden of the document preprocessing stage when building a RAG pipeline.
Original HWP/HWPX/PDF Parsing and a Single Pipeline for Document Structure Analysis
Hancom Data Loader uses proprietary HWP SDK technology to extract directly from the original without PDF conversion, and processes DLA, TSR, and OCR in a single pipeline. It supports HWP 3.0 through HWP 5.0, preserves various layout elements without loss, and the scope of applied technologies varies by format.
| Format | Processing Method | OCR | DLA | TSR |
| HWP, HWPX | Direct Parsing of Original Binary | ✔ (Optional) | ✔ (Optional) | ✔ (Optional) |
| Original processed extraction + OCR integration | ✔ | ✔ | ✔ | |
| OOXML | Text and basic structure extraction | – | – | – |
| PNG, JPG, BMP | OCR + DLA-based Recognition | ✔ | ✔ | ✔ |
Output formats and the scope of applied technologies vary by input format. OOXML is a format that includes document structure information, so you can generally extract text and basic structure. For detailed guidance by format, please contact us via Contact Hancom Data.
Level Inference Engine That Improves RAG Chunking Quality by Automatically Determining Paragraph Hierarchy
Hancom Data Loader analyzes paragraph styles, indentation, and numbering schemes to automatically tag hierarchy levels, helping preserve meaningful units during chunking as well. It’s optimized to recognize indentation-based hierarchy in Korean official documents, statutes, and reports, so it delivers particular strength in Korean document domains where global solutions are weak.
Container-based REST API, fully internalized on-premises, and responsive to security environments
Hancom Data Loader is fully self-contained within an internal network via a container-based REST API, meeting security requirements without external transmission. It can be operated as-is even in network-segmented and air-gapped (closed) environments, and the SaaS API approach can be integrated and used immediately without installation, making it suitable for fast pilots or small-scale tests.
From Reviewing Extraction Results to Post-Editing: Data Loader Studio
With Hancom Data Loader Studio, you can review and refine documents with low automatic extraction accuracy. You can compare, review, and edit the original and extracted results side by side, and train extraction patterns specialized for customer-specific forms—so the more non-standard documents you have, the greater the impact.
From Data Extraction to RAG Retrieval: A Single Stack Completed Through Hancompedia Integration
Extract documents with Hancom Data Loader, then have Hancompedia take over from chunking, embedding, and vector DB storage through RAG retrieval and Q—so you can build a single stack. Even customers without sufficient in-house RAG development capacity can implement a tailored system.
👉 Go use the Hancom Data Loader live demo
Frequently Asked Questions About Document Parsing Solutions
What’s the difference between a cloud-based document parsing API and an on-premises solution?
A cloud API processes documents by sending them to external servers, while on-premises is installed directly within the internal network with no external transmission. For organizations that require network segmentation, whether on-premises (self-contained) deployment is supported determines feasibility.
Why is a document parsing solution necessary in a RAG pipeline?
LLMs can’t read PDF, HWP/HWPX, and Microsoft Office documents as-is. A document parsing solution converts unstructured documents into structured data that AI can understand. If you build without parsing, tables, images, and hierarchical structure are lost before embedding, reducing retrieval accuracy.
What’s the first criterion to check when choosing a document parsing solution?
First, confirm the document formats you need to process and your security environment. If you use HWP/HWPX, prioritize whether direct parsing of the original is supported; if you operate in an air-gapped environment, prioritize whether fully on-premises (self-contained) deployment is possible.
RAG Pipeline: Check This Before Choosing a Document Parsing Solution
If you want to improve RAG quality, look at parsing before the LLM. If even one parsing criterion—format support, structural extraction, or security environment—doesn’t fit, quality is lost at every subsequent stage and can lead to a full rebuild after implementation.
In domestic environments, these criteria work differently. You need to be able to parse original HWP/HWPX, and you must be able to operate even in network-segmented and air-gapped environments. Most global solutions fail to meet these two conditions, ultimately leading to conversion workarounds or cloud dependency—resulting in both information loss and security risks. Korean enterprise and public-sector environments need a solution designed with these conditions as a premise from the start.
Hancom Data Loader supports original HWP/HWPX parsing and operates in network-separated and closed network environments.
- Direct parsing of original HWP/HWPX: Based on proprietary HWP SDK core technology, preserving the original layout and formatting elements without converting to PDF
- A single DLA·TSR·OCR pipeline: Fully internalized with no external dependencies, accurately extracting complex tables and multi-column layouts
- Level inference engine: Secures chunking quality by automatically tagging indentation-based hierarchy unique to Korean official documents and statutes
- Container-based API On-premises: Fully self-contained operation without external transmission in network-segmented and air-gapped environments
You can get started with Hancom Data Loader, the parsing solution optimized for the Korean document environment.
References
- Lewis et al., “Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks,” NeurIPS 2020
- Lin, “Revolutionizing Retrieval-Augmented Generation with Enhanced PDF Structure Recognition,” arXiv:2401.12599, 2024
- Zhang et al., “Document Parsing Unveiled: Techniques, Challenges, and Prospects for Structured Information Extraction,” arXiv:2410.21169, 2024
- AWS, “What is Retrieval-Augmented Generation (RAG)?”
- IBM, “What is RAG, Retrieval-Augmented Generation?”